


Doubao Responds to "Half of Compute for Binge-Worthy Dramas": ByteDance Video Generation Compute Is Only About 10%
Author: TechFlow
On October 19, 2026, according to reports from Jiemian News and other mainstream financial media outlets, Liu Xing, PR head for ByteDance’s AI large model “Doubao,” publicly addressed the recent claim that “more than half of China’s AI compute is being used to create binge-worthy micro-dramas,” stating directly that the assertion “lacks factual basis.” Liu disclosed that within ByteDance’s massive overall AI compute pool, only about 10% of compute resources are actually allocated to the training and inference of video generation models. This proportion fully accounts for frontier research and parameter tuning of underlying vision foundation models, contradicting online rumors that all of it is dedicated solely to short drama production. This clarification directly dispels the public misconception equating large model compute with the short drama bubble.
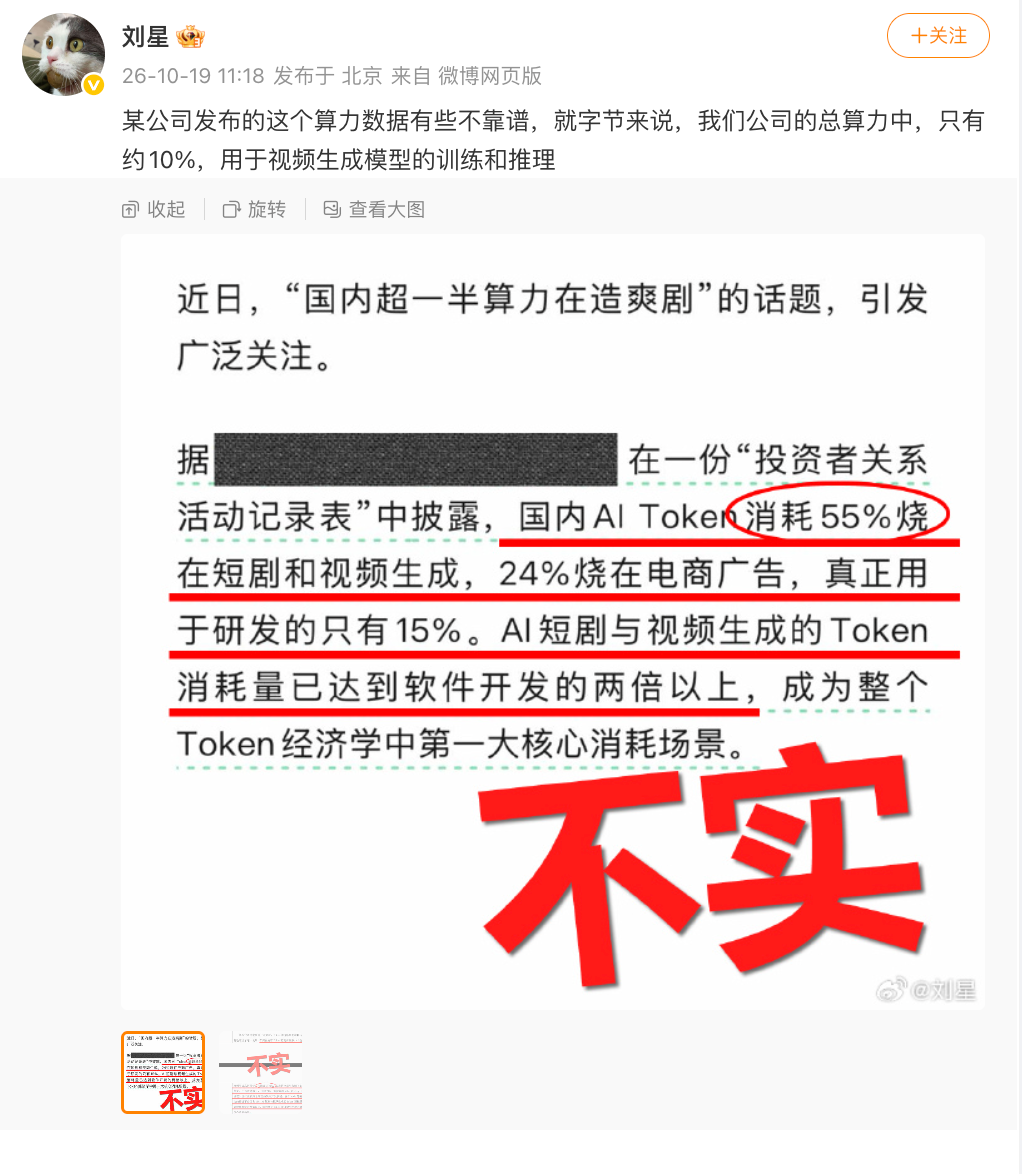
Concept Substitution During Report Data Circulation and Secondary Dissemination
The dispute was triggered by a set of figures disclosed by A-share listed company Chinese Online in its investor relations activity records. At the time, the company stated that 55% of domestic AI Token consumption originates from short dramas and video generation, 24% is used for e-commerce marketing, and software development accounts for only 15%. These minutes from institutional exchanges dating back several months were recently resurfaced by self-media, stripped of their specific context during propagation, and extrapolated into the claim that “half of China’s compute is used for making binge-worthy micro-dramas,” subsequently fueling macro-narrative binary emotional polarization.
This dissemination process contains obvious logical gaps. Chinese Online did not disclose the original research institution, industry sample coverage, or quantitative calculation models behind these nationwide estimates. Without a clearly defined statistical framework, elevating a localized inference from a specific business scenario directly to the overall compute distribution across the entire industry has caused a distorted perception of the domestic generative AI industrial landscape among investors.
Physical Decoupling Between Token Throughput and Chip Compute Load
Equating Token consumption directly with hardware compute utilization is fundamentally unsound from a computer science perspective. In the operational mechanisms of multimodal and large language models, autoregressive computation for text sequence generation and intensive matrix rendering for video diffusion models follow entirely different physical load characteristics. Billing tokens calculated by certain cloud services and application-layer platforms per video frame primarily serve as commercial pricing units and cannot be directly reverse-engineered into underlying data center GPU cluster floating-point computation time or VRAM bandwidth consumption.
Within major domestic cloud computing and intelligent computing centers, the vast majority of compute clusters continue to fully support the pre-training of trillion-parameter multimodal general-purpose large models, code assistance, search and recommendation algorithm tuning, and industrial end-to-end model inference. Conflating high-frequency application-layer Token traffic with the highly compute-intensive training of underlying models completely diverges from the reality of actual data center resource allocation.
The Structural Landscape of China’s Actual Generative AI Industrial Implementation
The application spectrum of video generation technology extends far beyond the single category of micro-dramas. Vision foundation models developed by ByteDance, Kuaishou, and several cutting-edge multimodal startups are extensively penetrating high-value chains such as film and television post-production automation, digital asset modeling, cross-border e-commerce material rendering, and scientific graphical simulation. Micro-dramas are merely an early validation format for video generation technology in the consumer internet sector, rather than the absolute main driver of compute consumption.
Under the objective environment where underlying compute supply faces external constraints, top domestic tech giants maintain strict discipline over capital expenditures and output efficiency. Resource allocation focuses consistently on generational leaps in foundational general model capabilities and empowerment through enterprise-grade productivity tools.
Currently, leading domestic large model vendors are accelerating the commercial deployment of multimodal interactive models. Officially calculated data on model call volumes and enterprise-level inference costs for the latest period will be successively disclosed in the industry earnings season later this month.
Join TechFlow official community to stay tuned
Telegram:https://t.me/TechFlowDaily
X (Twitter):https://x.com/TechFlowPost
X (Twitter) EN:https://x.com/BlockFlow_News
 深潮TechFlow














